
What Is Robots.txt?
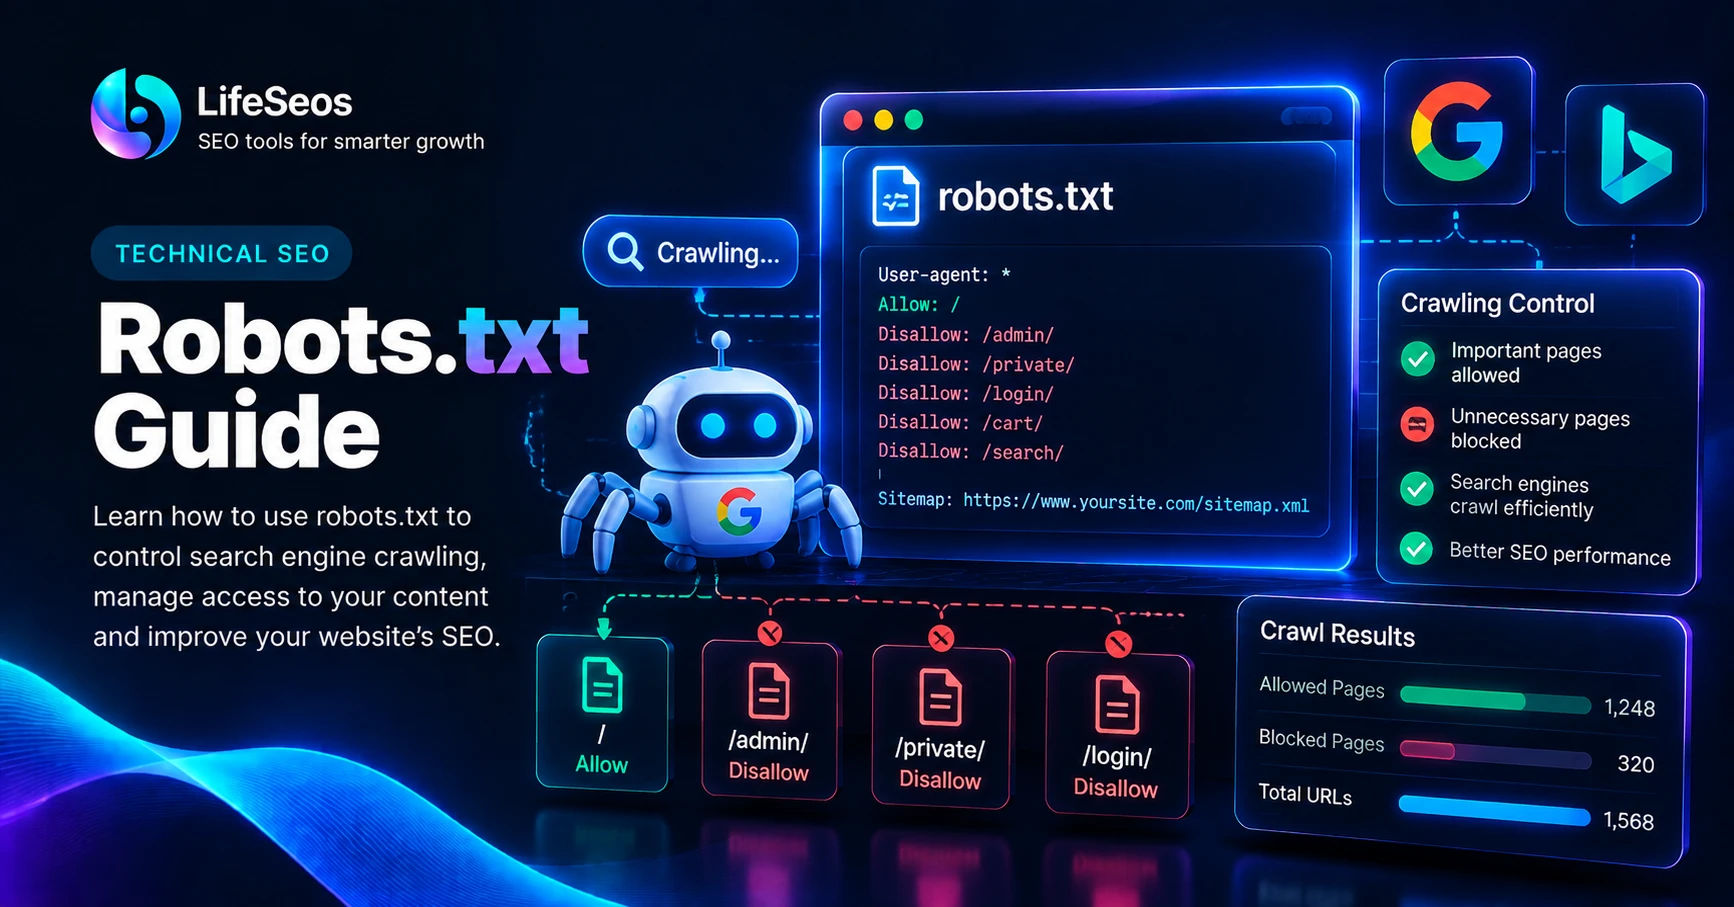
Robots.txt is a plain text file that provides crawling instructions to supported search engine bots and other automated crawlers.
It is normally placed at the root of a website, such as yourdomain.com/robots.txt, so crawlers can check the file before requesting other website resources.
The file can be used to allow or restrict crawler access to specific paths, folders or sections of a website.
Robots.txt is primarily a crawl management tool. It should not be treated as a security feature or as a reliable method for removing pages from search results.
- Controls crawler access to website paths
- Uses simple text-based directives
- Can target specific crawlers
- Can reference an XML sitemap
- Supports crawl management
- Does not protect private information
Where Is the Robots.txt File Located?
The robots.txt file should normally be accessible from the root of the website.
For example, if your website is https://example.com, the robots.txt file would usually be available at https://example.com/robots.txt.
Placing the file in another folder does not provide the same site-wide crawling instructions.
The file should also be reachable without login requirements or unnecessary redirects.
- Use the root domain location
- Make sure the file loads publicly
- Avoid requiring authentication
- Use a stable URL
- Check the file after major hosting or routing changes
How Does Robots.txt Work?
When a supported crawler visits a website, it can request robots.txt and interpret the rules that apply to its user agent.
Rules are usually grouped by user agent and can include Allow and Disallow directives.
A rule can apply to every supported crawler or only to a specific crawler.
Because different crawlers may interpret unsupported directives differently, keep the file simple and rely on documented rules.
- User-agent identifies the crawler
- Disallow restricts crawling of matching paths
- Allow can permit a more specific path
- Sitemap can reference the XML sitemap location
- Rules are evaluated by compatible crawlers
Understanding the User-agent Directive
The User-agent directive identifies which crawler a set of robots.txt rules applies to.
An asterisk can be used to represent all compatible crawlers, while a specific crawler name can be used when a rule should apply only to that crawler.
Most websites can use a simple general rule unless there is a clear reason to handle a specific crawler differently.
Avoid creating unnecessary crawler-specific rules because they can make the file harder to review.
- User-agent: * — applies to all supported crawlers
- Specific user agents can have separate rules
- Keep general rules simple
- Avoid unnecessary crawler-specific configuration
Allow and Disallow Rules
Disallow rules tell supported crawlers which matching paths should not be crawled.
Allow rules can be used to permit a more specific path within an otherwise restricted section when supported by the crawler.
The path in the rule matters. A small mistake can block more content than intended.
Always review the effect of broad rules before publishing them to a production website.
- Disallow: /private/ — restricts crawling of the matching folder
- Disallow: / — can block crawling across the entire site
- Allow rules can create specific exceptions
- Broad rules should be reviewed carefully
- Path matching should be tested before deployment
Add Your XML Sitemap to Robots.txt
Robots.txt can include the location of your XML sitemap.
This gives compatible crawlers another way to discover the sitemap URL.
The sitemap should still be publicly accessible and contain accurate canonical URLs.
Referencing a sitemap in robots.txt does not replace submitting it through search engine webmaster tools.
- Use the complete sitemap URL
- Use the preferred HTTPS version
- Make sure the sitemap loads successfully
- Keep the sitemap location accurate
- Submit the sitemap separately when appropriate
Why Is Robots.txt Important for SEO?
Robots.txt can influence how search engine crawlers spend time on different areas of a website.
For many small websites, crawl management is simple because most public pages should remain accessible.
Larger websites may use robots.txt to reduce crawling of low-value technical URLs, filters or repeated resource paths.
The most important SEO concern is avoiding accidental blocking of valuable content.
- Helps manage crawler access
- Can reduce unnecessary crawling
- Supports cleaner technical configuration
- Can reference the XML sitemap
- Helps avoid crawling certain technical paths
- Requires careful maintenance
Robots.txt vs Noindex
Robots.txt and noindex solve different problems and should not be confused.
Robots.txt controls whether a supported crawler may access a URL or path.
A noindex directive requests that a page not be included in search results after the search engine can access and process the directive.
If crawling is blocked in robots.txt, the crawler may not be able to see a noindex directive placed on the page itself.
- Robots.txt controls crawling
- Noindex controls indexing behavior
- Blocking crawling does not automatically remove a URL from search
- A crawler may need access to see a noindex directive
- Choose the method based on the actual goal
Robots.txt Is Not a Security Tool
Robots.txt is publicly accessible and its rules are visible to anyone who opens the file.
It does not prevent a person from visiting a URL directly, and not every automated bot is required to follow robots.txt instructions.
Sensitive resources should be protected using proper authentication, authorization and server-side access controls.
Listing a private path in robots.txt can even make that path easier for someone to notice.
- Do not store secrets in robots.txt
- Do not rely on robots.txt for access control
- Protect private pages with authentication
- Use server-side permissions for sensitive resources
- Remember that the file itself is public
Common Robots.txt Mistakes
Robots.txt files are usually short, but small mistakes can have large effects.
The most serious errors involve accidentally blocking important pages or assuming that crawl restrictions provide security or indexing control.
Review the file after major website migrations, routing changes or framework updates.
- Blocking the entire website accidentally
- Blocking important public pages
- Using incorrect path rules
- Using robots.txt as a security mechanism
- Assuming blocked pages cannot appear in search
- Using outdated sitemap URLs
- Adding unnecessary complex rules
- Forgetting to review rules after site changes
A Simple Robots.txt Example
A basic robots.txt configuration is often enough for a small public website.
For example, you may allow normal crawling while restricting internal application areas and referencing the XML sitemap.
The exact rules should always match the real structure of the website rather than being copied blindly from another domain.
- User-agent: *
- Disallow: /admin/
- Disallow: /api/
- Sitemap: https://example.com/sitemap.xml
How to Test Robots.txt Changes
Testing should be part of every important robots.txt change.
Before publishing a new rule, identify the URLs that should remain crawlable and the URLs that should be restricted.
After deployment, open the robots.txt file directly and confirm that the production version contains the intended rules.
Monitor search engine crawling and indexing reports for unexpected changes after significant updates.
- Review the rule before publishing
- Test important URLs
- Confirm the production robots.txt file
- Check sitemap references
- Monitor search engine reports
- Investigate unexpected indexing changes
Robots.txt on Modern Frameworks
Many modern website frameworks can generate robots.txt automatically instead of requiring a manually maintained text file.
This can reduce maintenance when routes or environments change, but the generated output should still be reviewed.
For example, a production website may allow public content while restricting admin, authentication or API routes.
The method used to generate robots.txt matters less than whether the final public file contains accurate rules.
- Static robots.txt files are simple to maintain
- Framework-generated files can update automatically
- Review generated output in production
- Keep development and production rules separate when necessary
- Verify restricted paths carefully
A Practical Robots.txt Workflow
A simple workflow helps reduce the risk of accidental crawler blocking.
Start by identifying which website sections should remain public and which technical areas genuinely do not need crawling.
Keep the file minimal, test the rules and review the production result after deployment.
- Step 1 — List important public pages
- Step 2 — Identify technical paths that may not need crawling
- Step 3 — Create simple User-agent and Disallow rules
- Step 4 — Add the sitemap URL
- Step 5 — Check for broad accidental blocks
- Step 6 — Test important URLs
- Step 7 — Publish the file
- Step 8 — Review the live robots.txt
- Step 9 — Monitor crawling and indexing reports
Final Robots.txt SEO Checklist
A well-configured robots.txt file helps manage crawler access without interfering with important public content.
The file should remain simple, accurate and aligned with the current structure of the website.
Review robots.txt whenever major routing, migration or indexing changes are made.
- The robots.txt file loads publicly
- Important public pages are not blocked
- Broad Disallow rules have been reviewed
- Private content uses real access controls
- Robots.txt is not being used as a noindex replacement
- The sitemap URL is correct
- Rules match the current site structure
- Production output has been tested
- The file is reviewed after major website changes
Put this guide into practice
Open the related LifeSeos tool and apply what you just learned to your own website.
Robots.txt Generator